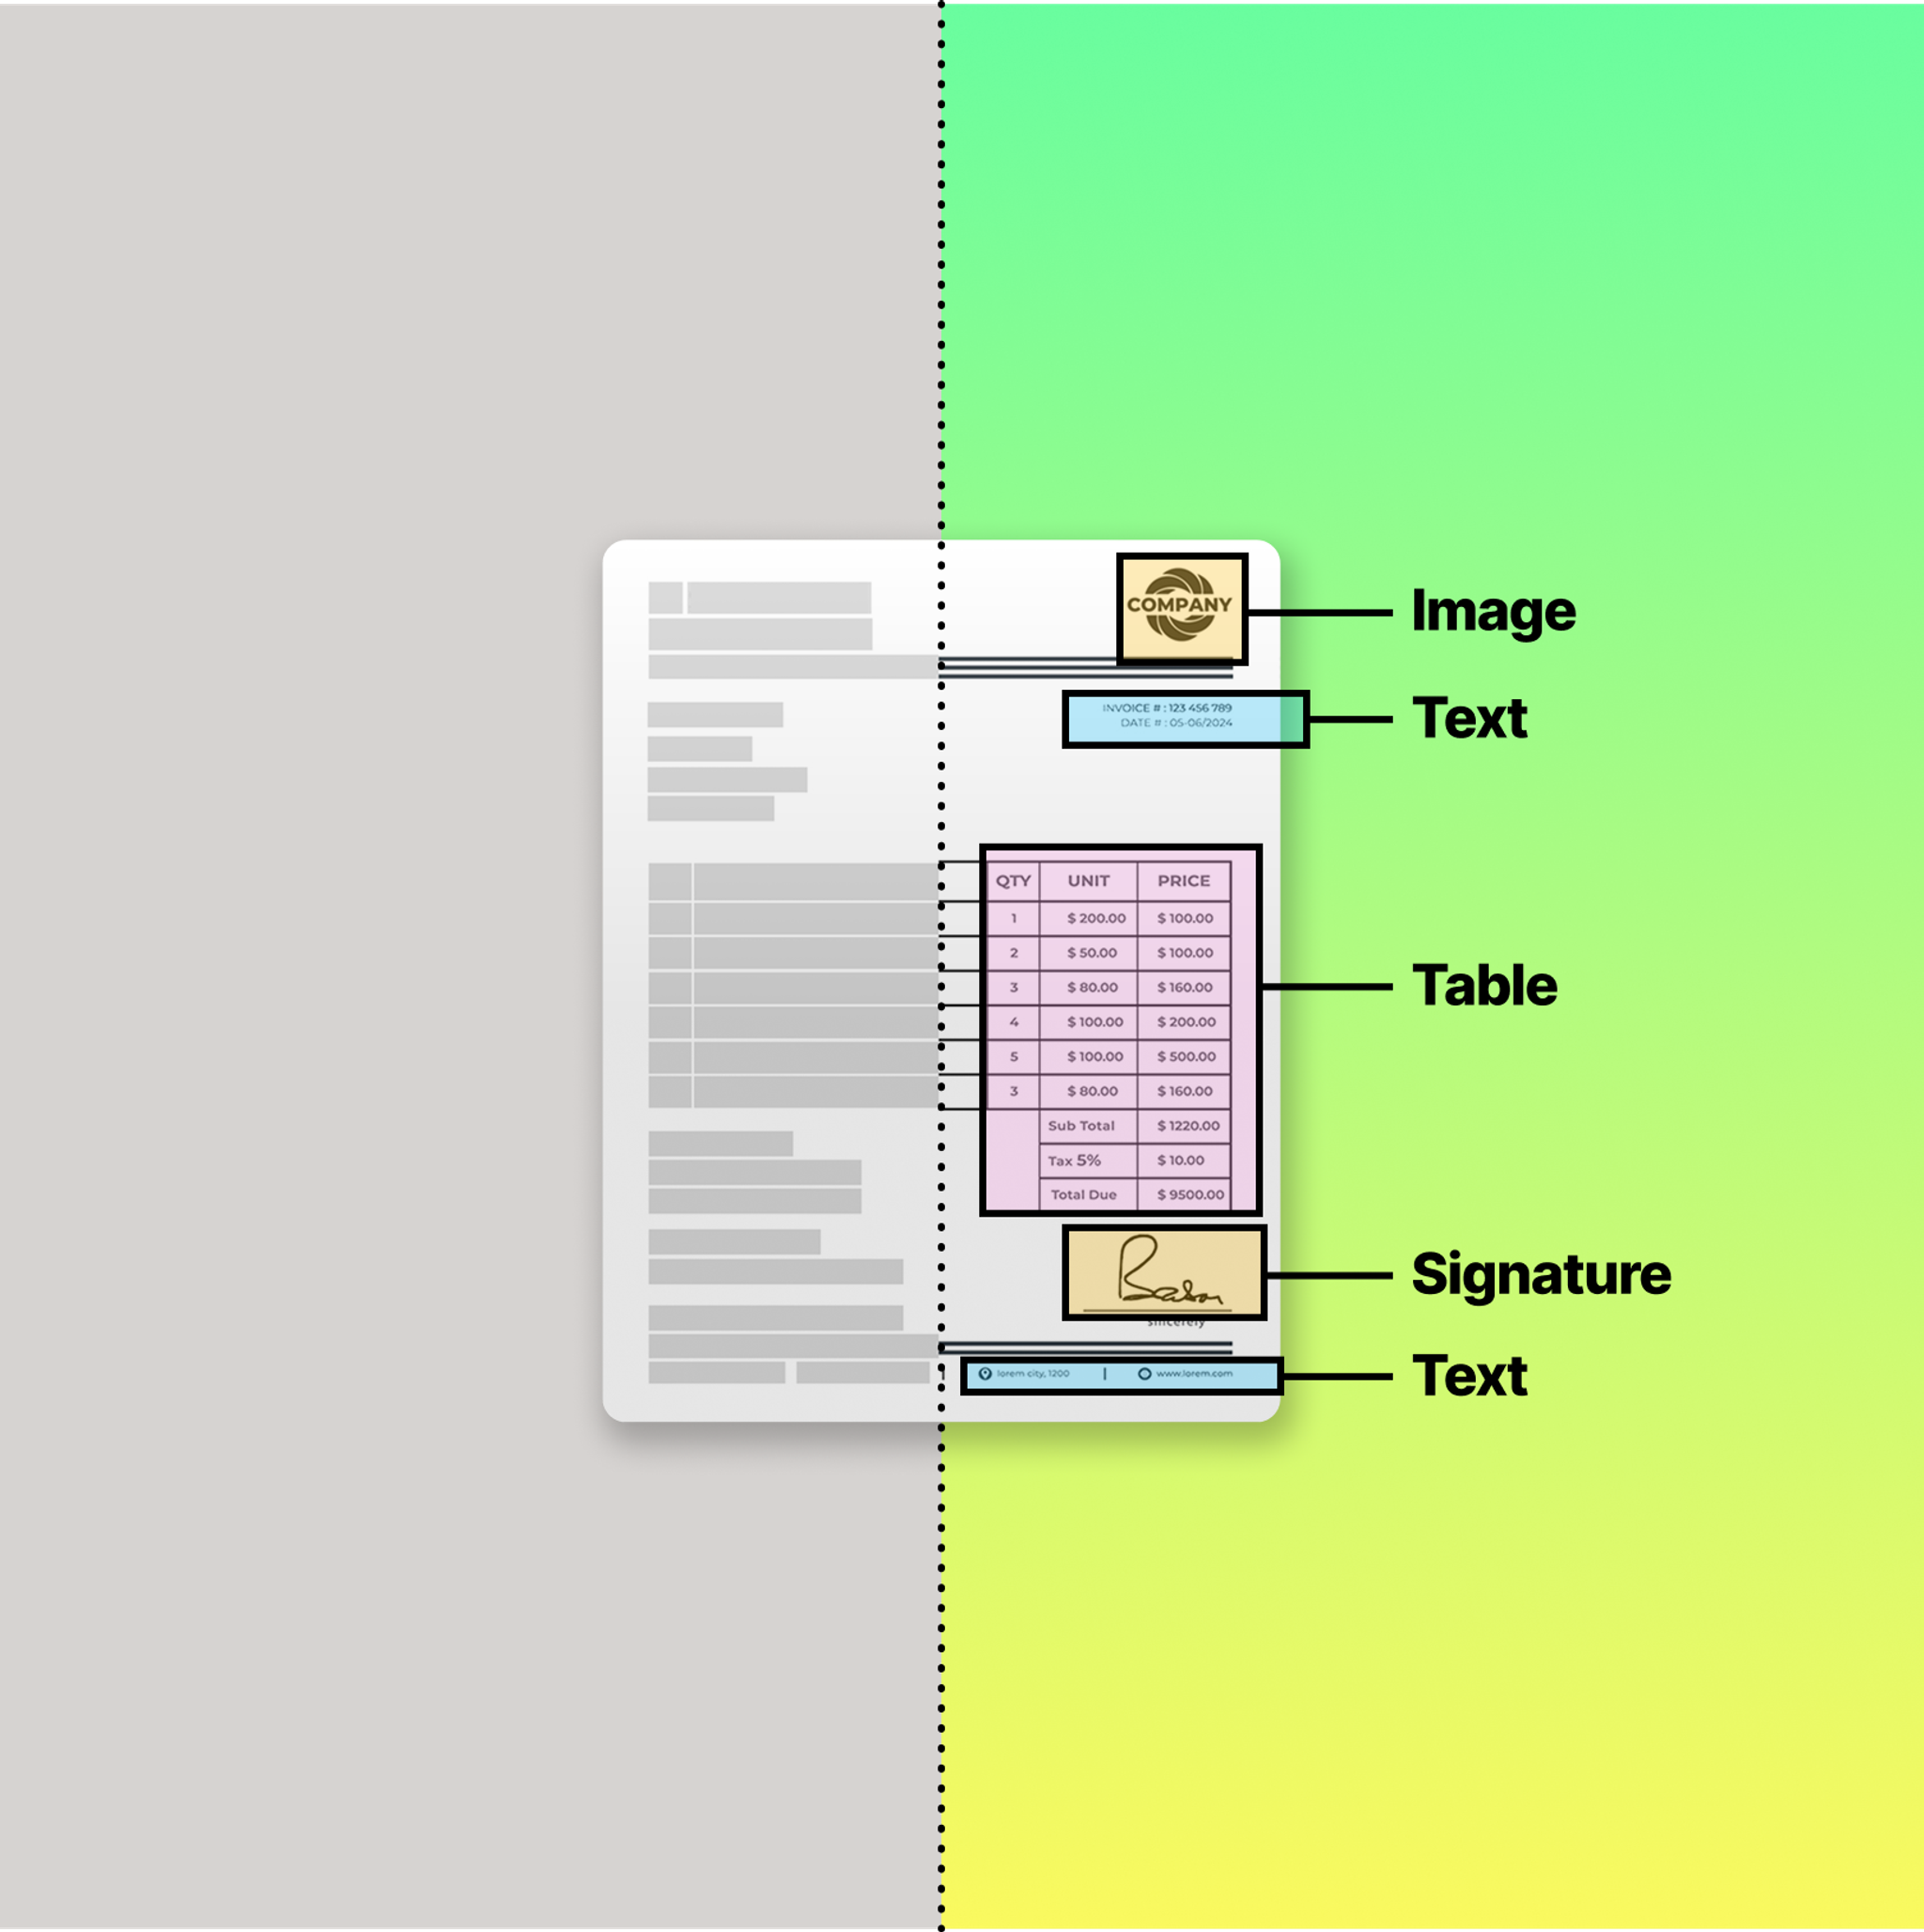
We structure your unstructured data.
Parse PDFs, tables, forms and scans into structured data your agents can trust.
Trusted by the Fortune 500
Point. Parse. Done.
Every file is different, and Unstructured knows how to handle each one. It automatically applies the right processing strategy, turning complex files into structured, agent-ready data with no manual setup.

Transformation,
tailored to fit.


Manufacturing
From technical manuals to engineering drawings to supplier specs, Unstructured helps manufacturers turn dense technical documents into structured, searchable data.

Insurance
From ACORD forms to policy contracts to claims paperwork, Unstructured helps insurers turn form-heavy, handwritten, and scanned documents into structured, GenAI-ready data for faster underwriting and claims.
Meet the teams
putting their data
to work.
SAP, IBM, Intel, Teradata and Uniphore use Unstructured to turn complex documents into production-ready AI data.
Purpose-built
for complex docs.
for complex docs.
Scanned forms, dense tables, handwriting and multi-column PDFs need more than a generic parser. Unstructured extracts every page with its tables, layout and reading order intact.
Table Accuracy
Extracts complex tables without losing structure.
Content Accuracy
Preserves your documents as they were written.
Lowest Hallucination Rate
Keeps extracted content grounded in the source.
It just works.
Everything you need to transform complex documents, without the complexity of building it yourself.
- TABLES
Table extraction that preserves structure.
Preserve rows, columns, headers, and relationships—even across complex, multi-page tables.
- OCR
OCR that catches every detail.
Capture text from scans, images, handwriting, and low-quality documents with high accuracy.
- COMPLEX LAYOUTS
Layout intelligence that keeps context.
Preserve reading order, hierarchy, sections, and relationships across every page.
Enterprise at every level.
Cloud or private. Out of the box or deeply customized. Unstructured adapts to the way your enterprise works.
FAQs
Answers to our most common questions.
For one clean file, go ahead. But across thousands of messy docs that keep changing, the model burns tokens fighting the layout instead of answering. Unstructured cleans and structures them first, so you get better answers for less.
Nope. PDFs are one of 50+ file types, alongside Word, Excel, PowerPoint, email, HTML, images, and scans, all through one pipeline. Whatever format your data shows up in, it comes out clean and structured.
Parsing is the easy part. The real work is connecting to your sources, then chunking, embedding, and loading the result into your database, on a schedule, at scale. A parser handles one file. Unstructured runs the whole pipeline.
Yes. Connect to 20+ sources (S3, SharePoint, Drive, Snowflake, Databricks, and more) and write to 20+ destinations, including every major vector database. You connect the ends; the pipeline runs between them. No glue code.
Yeah, this is built for regulated data. It's SOC 2 Type 2, HIPAA, GDPR, ISO 27001, and FedRAMP High and it can run on shared Business SaaS, a dedicated isolated instance, or fully in your own VPC. If your security or compliance team wants the full picture, book a call and we'll walk you through it.
Depends on your industry. Finance teams pull fields off loan files and contracts and stand up research copilots; insurance turns claims and forms into clean, structured data; legal extracts and checks contract terms; life sciences preps research papers for discovery; manufacturing makes dense technical manuals searchable. Different industries, same job: turn a pile of messy documents into something an AI can actually use.
Reach us at support@unstructured.io, or if you'd rather just talk it through, book a call and we'll take it from there.
Get started today.
Install Unstructured in minutes and turn any file into structured, agent-ready data.